publications
Publications in reverse chronological order. * indicates equal contribution or co-first authorship.
Research map
How the papers connect
Each node is a paper. Select a topic or paper to trace the shared methods and application areas across my research.
An interactive network of publications grouped into wearable cardiac monitoring, AI for Scientific Discovery and Clinical Decision Aid, and Interpretable AI.
All publications
2026
-
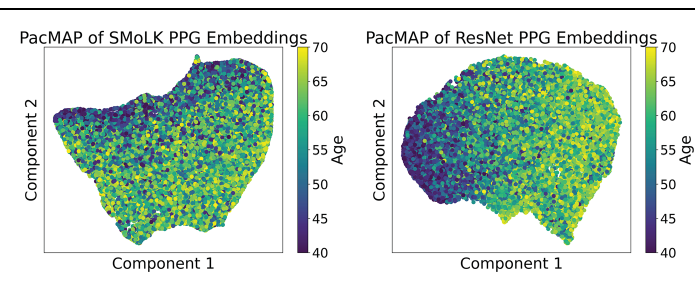 npj Artificial Intelligence, 2026
Abstract
“Data hugging” blocks independent verification of medical AI. Apple claims age estimation with a mean absolute error of 2.9 years using photoplethysmographic (PPG) signals. Given PPG’s noise, such accuracy is questionable, raising concerns about other tech companies’ claims. Using UK Biobank data, we find this accuracy unreplicable, achieving results only marginally better than predicting mean age. We advocate for curated public benchmark datasets and evaluation platforms to protect the public from unverifiable claims.
-
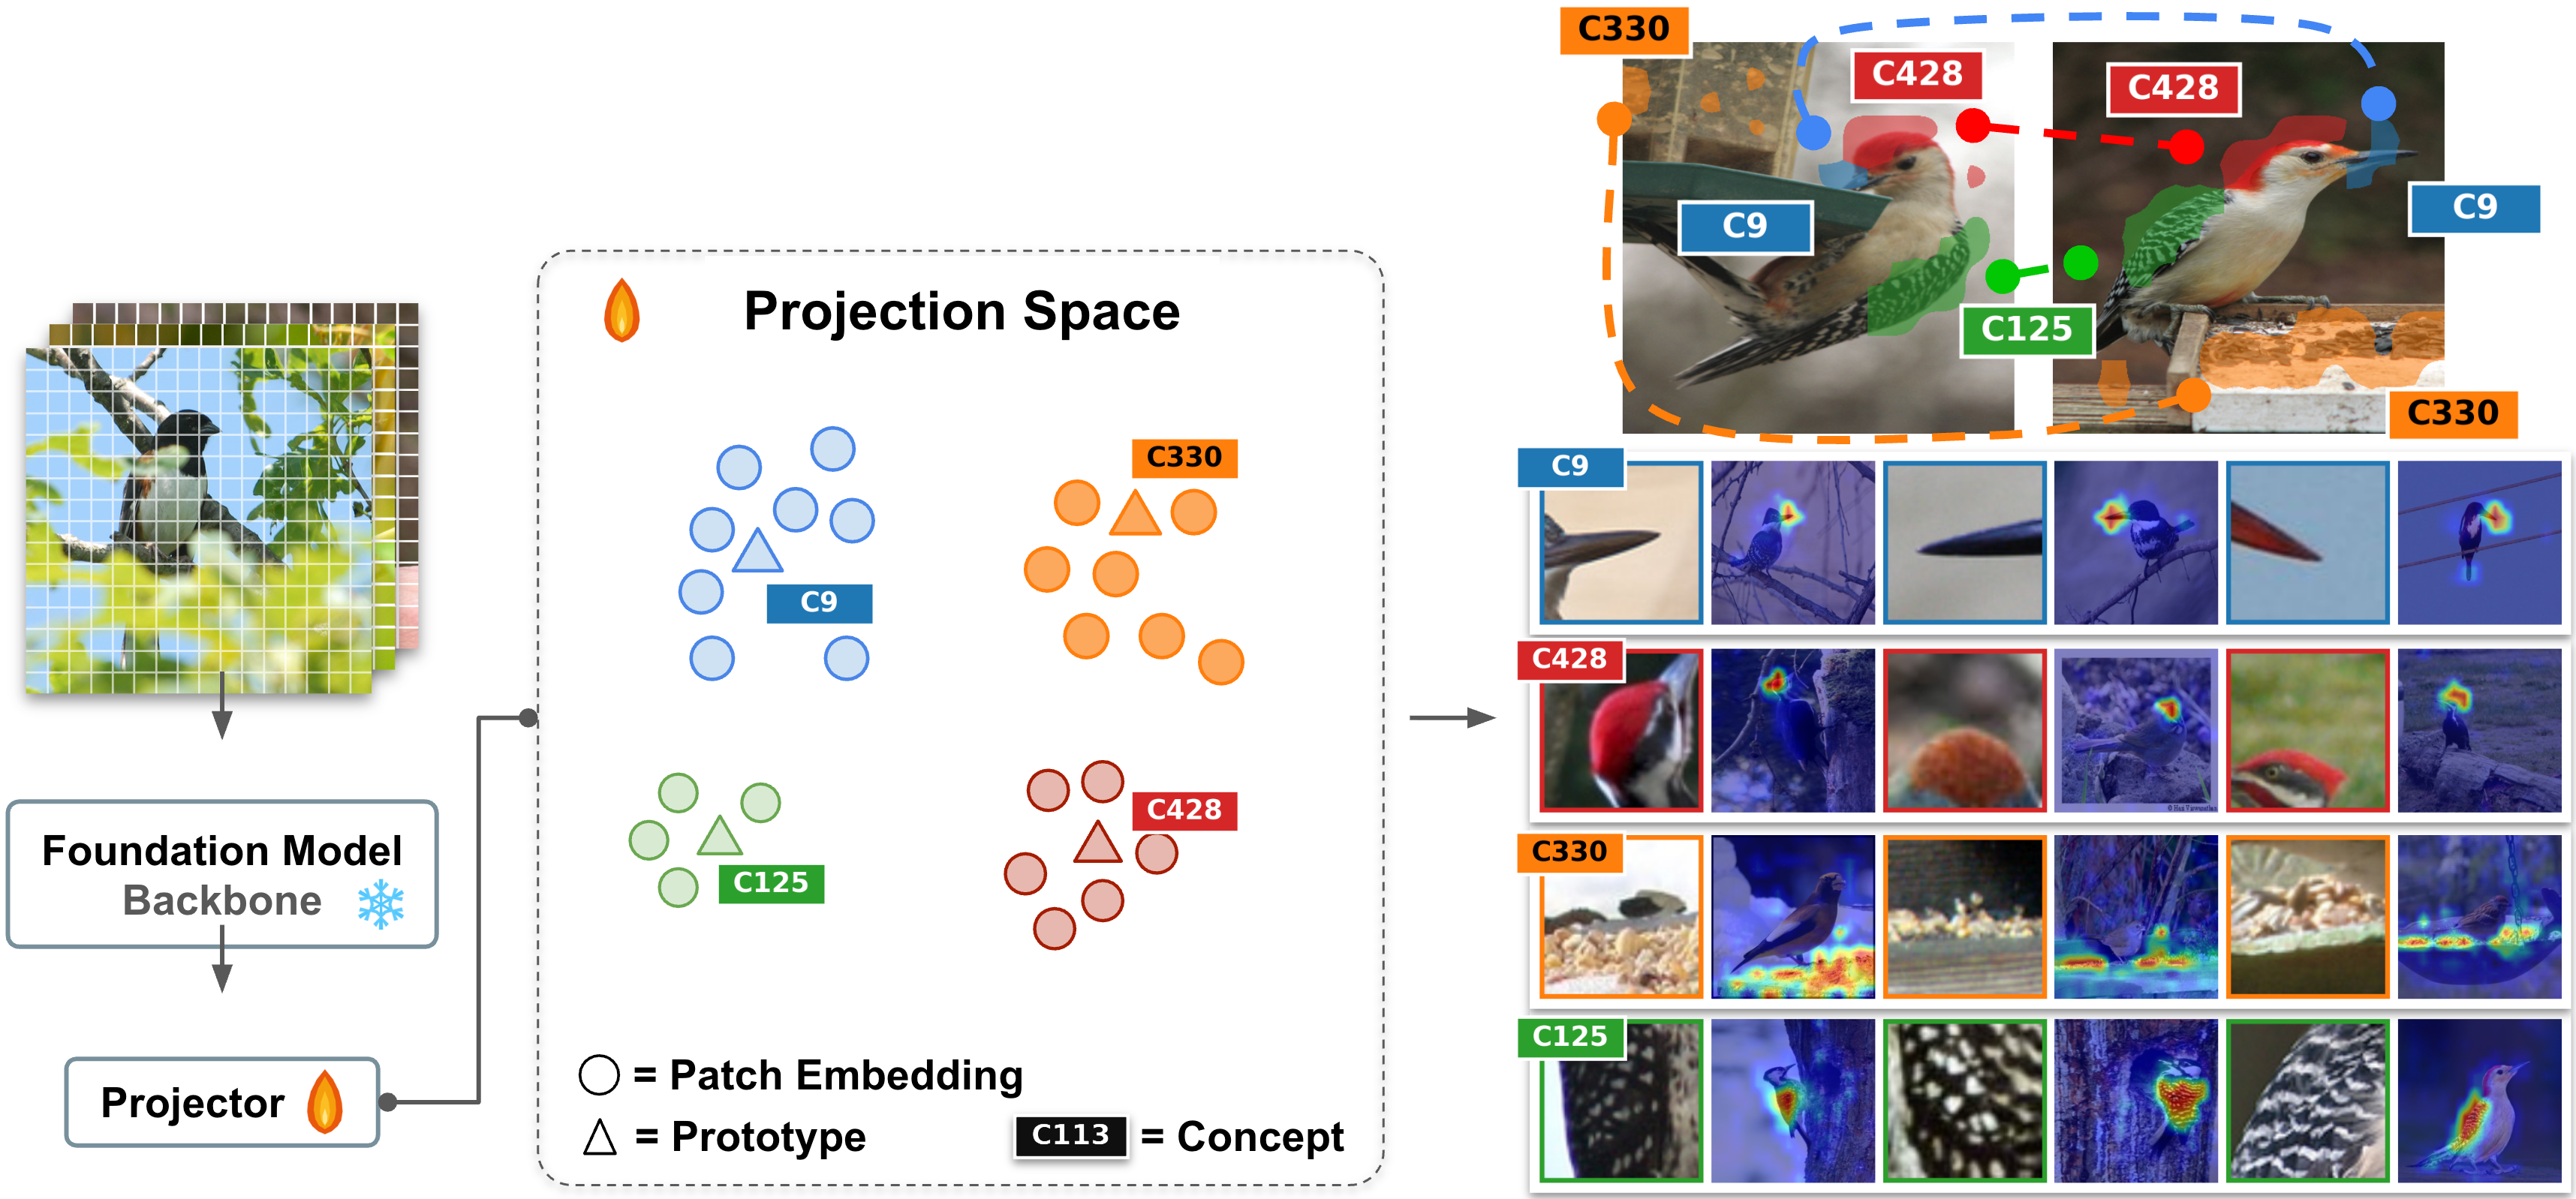 ProtoCDisco: Unsupervised Concept Discovery Using Foundation Model RepresentationsManuscript in submission, 2026
Abstract
Visual concept discovery aims to identify recurring visual patterns in data, providing a structured vocabulary for describing visual content. However, in learned representations, concepts are not explicitly defined: they remain hidden within high-dimensional features, without clear structure. Existing approaches attempt to uncover such concepts through post-hoc discovery methods, supervised prototype-based models, or clustering-based approaches, but typically fail to simultaneously achieve spatial precision, unsupervised discovery, and semantic consistency across images. We propose ProtoCDisco, a lightweight framework that discovers visual concepts from foundation model representations without supervision. Our method learns a set of prototype anchors in a structured feature space, yielding precise concepts that are spatially coherent (consistently localized across images), distinct (minimally overlapping), and complete (preserving the backbone’s discriminative power). Across diverse domains and backbones, our concepts match or exceed k-means, MCD, CRAFT and RA-SAE baselines on downstream classification performance, while being significantly more coherent and distinct. We also show in human evaluation that our method receives significantly higher ratings for semantic consistency, spatial specificity, and interpretability, with greater inter-rater agreement than baselines.
-
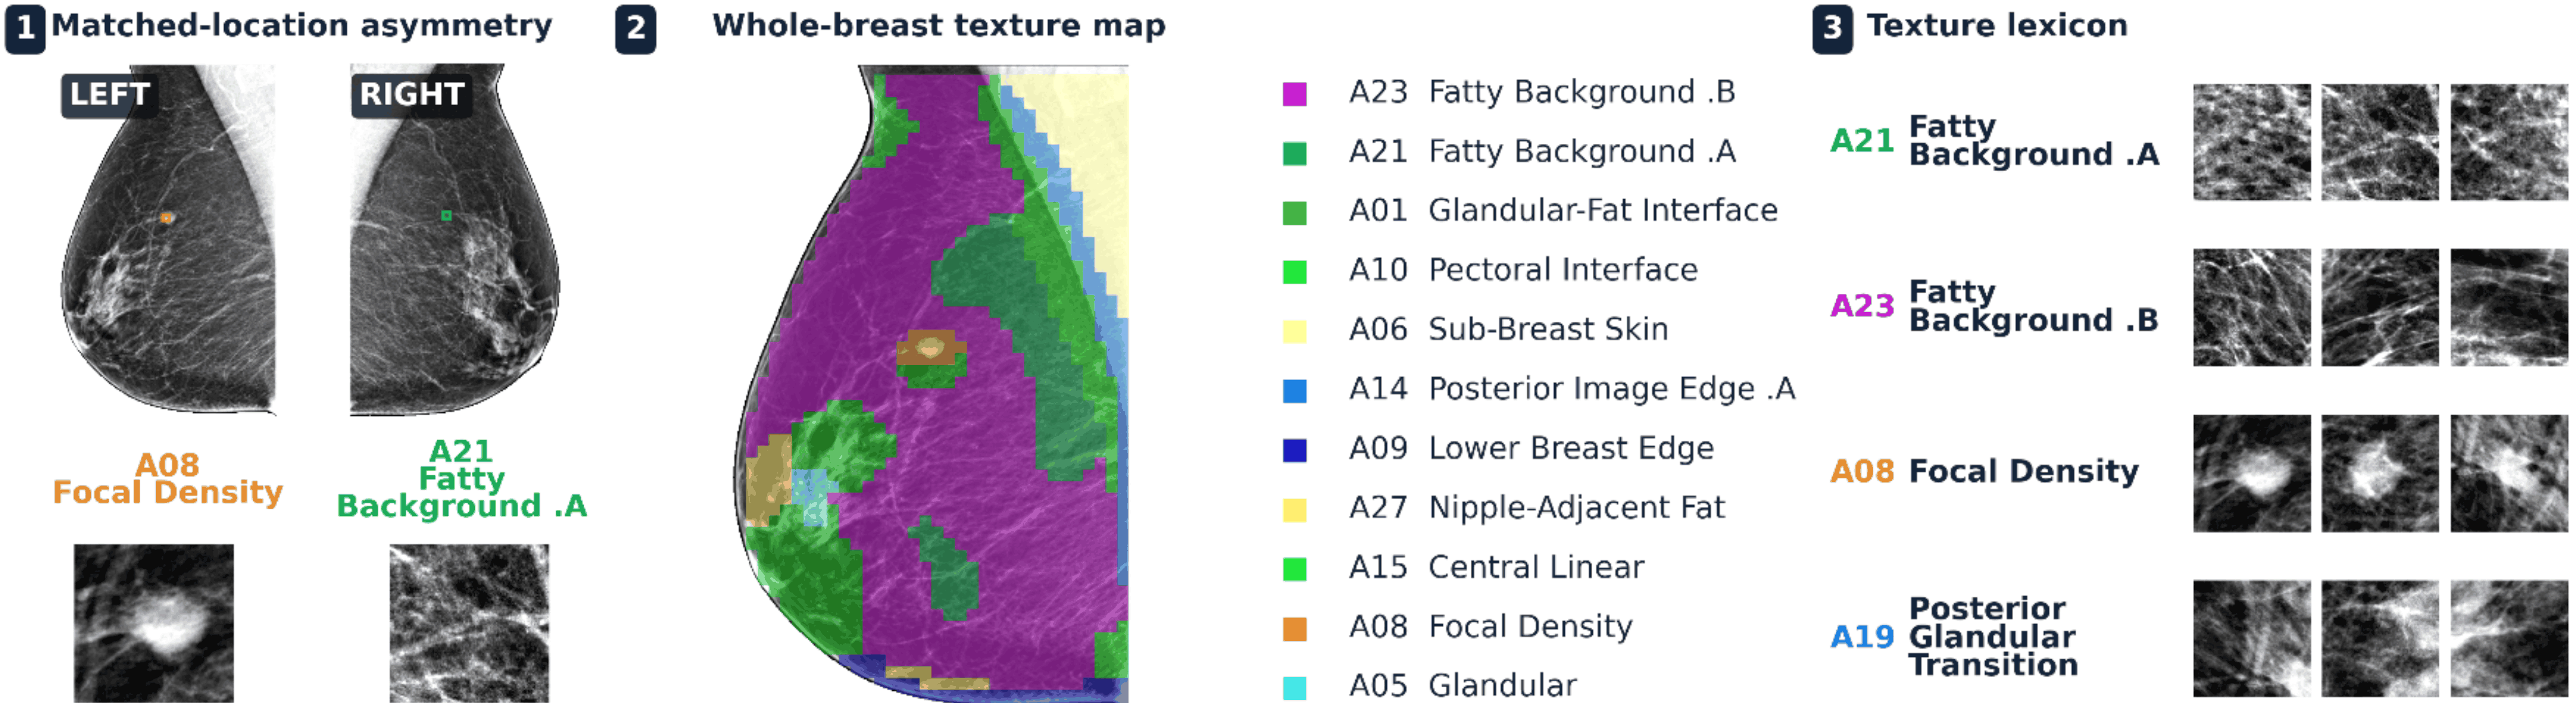 A Mammographic Texture Lexicon for Interpretable Breast Cancer Risk PredictionOngoing research, 2026
Work in progress.
-
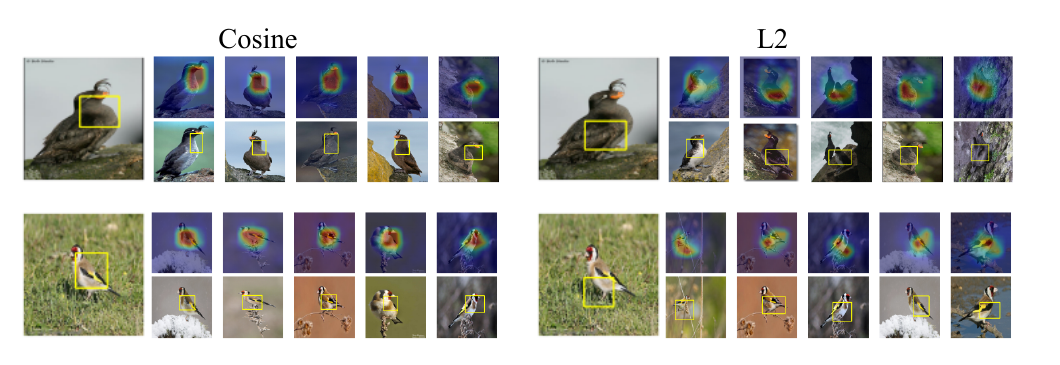 In Proceedings of the IEEE/CVF Winter Conference on Applications of Computer Vision, Mar 2026
Abstract
Prototypical-part networks are a popular interpretable alternative to black-box deep learning models for computer vision because of their faithful, prototype-based self-explanations. However, in practice, they have proven difficult to train because they are highly sensitive to hyperparameter tuning and difficult to comprehend because they contain a large number of prototypes. We show that replacing ℓ₂ distance with an angular prototype similarity in the original ProtoPNet greatly improves robustness to hyperparameter selection and is sufficient to produce accuracy and sparsity competitive with state-of-the-art on many backbones and datasets. We also show cosine similarity leads to superior accuracy for five different ProtoPNet architectures (ProtoPNet, TesNet, Deformable ProtoPNet, ProtoTree, and ST-ProtoPNet). Finally, we demonstrate ProtoPNet with cosine similarity produces better semantics than ℓ₂: prototypes from cosine models score better on prototype quality metrics and are perceived as more similar 3:2 in a user study.


2025
-
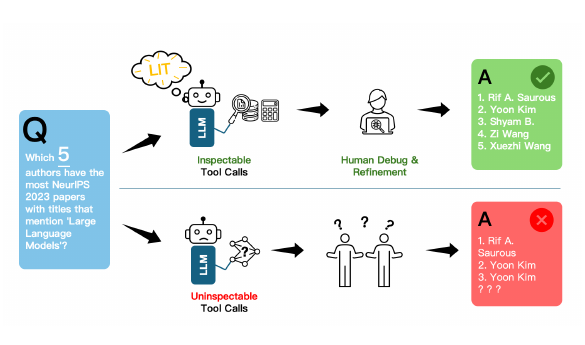 In Multi-Turn Interactions in Large Language Models Workshop (MTI-LLM Workshop, NeurIPS), 2025
Abstract
Large language models (LLMs) have exhibited remarkable capabilities across various domains. The ability to call external tools further expands their capability to handle real-world tasks. However, LLMs often follow an opaque reasoning process, which limits their usefulness in high-stakes domains where solutions need to be trustworthy to end users. LLMs can choose solutions that are unreliable and difficult to troubleshoot, even if better options are available. We address this issue by forcing LLMs to use external – more reliable – tools to solve problems when possible. We present a framework built on the tool-calling capabilities of existing LLMs to enable them to select the most reliable and easy-to-troubleshoot solution path, which may involve multiple sequential tool calls. We refer to this framework as LIT (LLMs with Inspectable Tools). In order to support LIT, we introduce a new and challenging benchmark dataset of 1,300 questions and a customizable set of reliability cost functions associated with a collection of specialized tools. These cost functions summarize how reliable each tool is and how easy it is to troubleshoot. For instance, a calculator is reliable across domains, whereas a linear prediction model is not reliable if there is distribution shift, but it is easy to troubleshoot. A tool that constructs a random forest is neither reliable nor easy to troubleshoot. These tools interact with the Harvard USPTO Patent Dataset and a new dataset of NeurIPS 2023 papers to solve mathematical, coding, and modeling problems of varying difficulty levels. We demonstrate that LLMs can achieve more reliable and informed problem-solving while maintaining task performance using our framework.
-
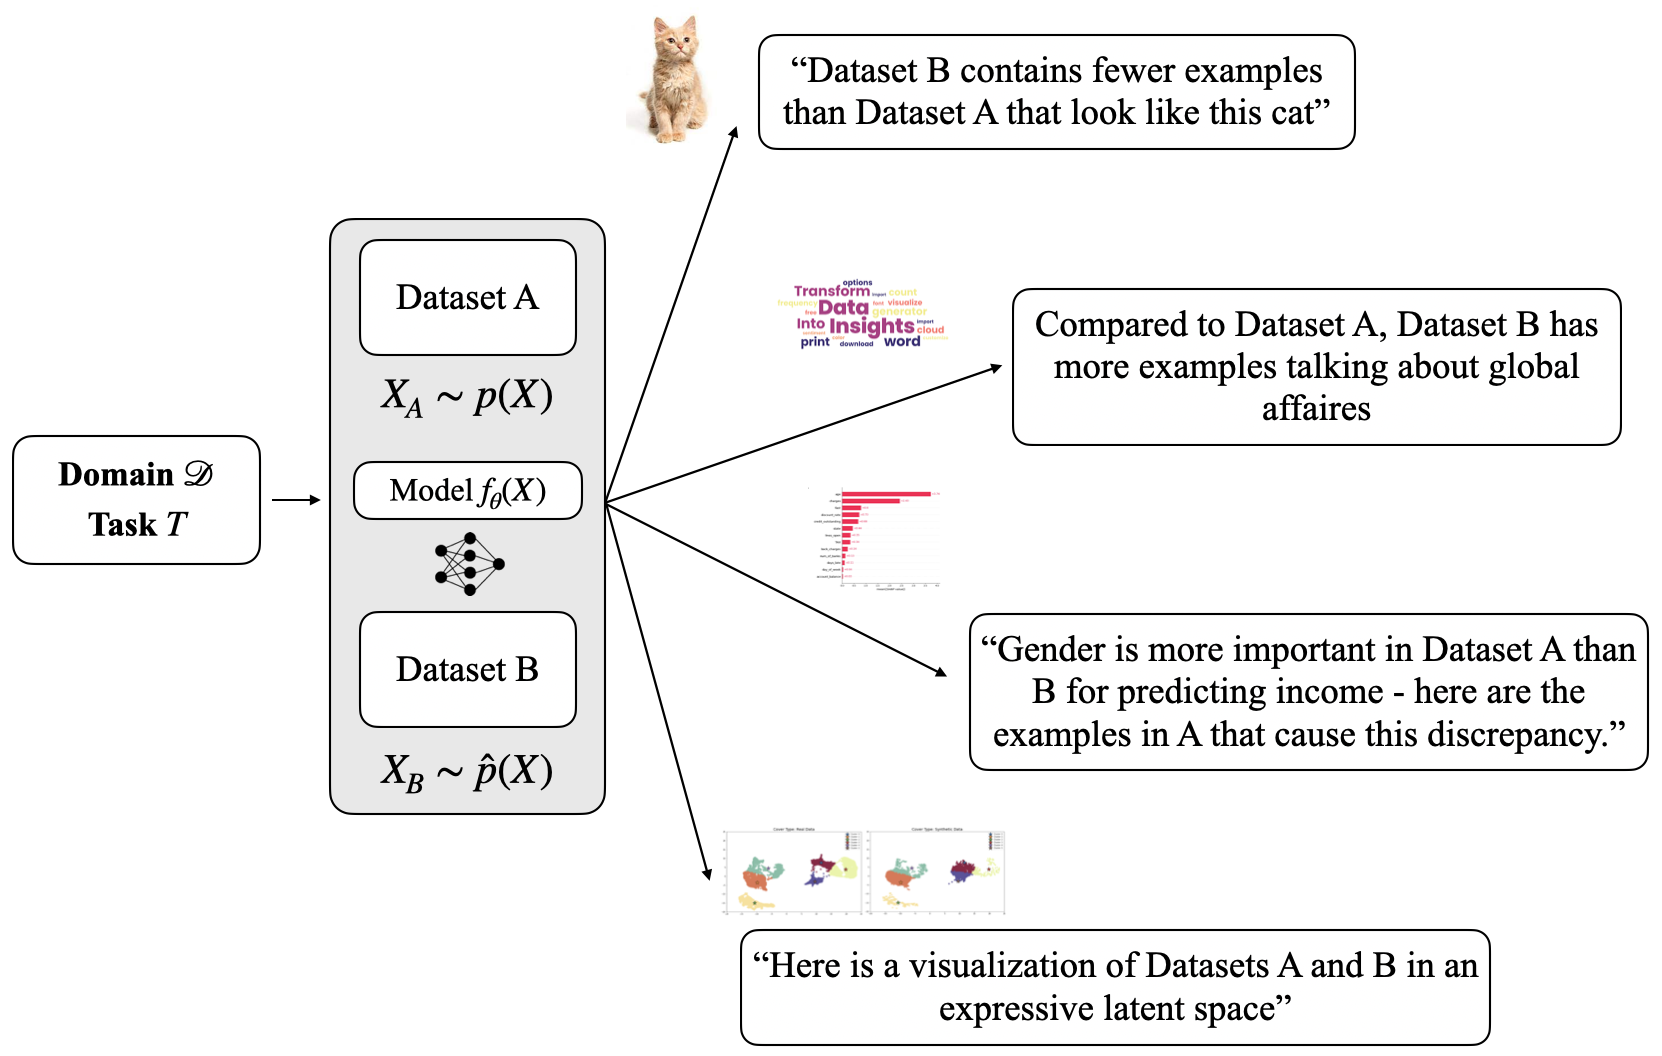 Journal of Machine Learning Research, 2025
Abstract
The performance of machine learning models relies heavily on the quality of input data, yet real-world applications often face significant data-related challenges. A common issue arises when curating training data or deploying models: two datasets from the same domain may exhibit differing distributions. While many techniques exist for detecting such distribution shifts, there is a lack of comprehensive methods to explain these differences in a human-understandable way beyond opaque quantitative metrics. To bridge this gap, we propose a versatile framework of interpretable methods for comparing datasets. Using a variety of case studies, we demonstrate the effectiveness of our approach across diverse data modalities—including tabular data, text data, images, time-series signals – in both low and high-dimensional settings. These methods complement existing techniques by providing actionable and interpretable insights to better understand and address distribution shifts.
-
 In Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, Jun 2025
Abstract
Interpretability is critical for machine learning models in high-stakes settings because it allows users to verify the model’s reasoning. In computer vision, prototypical part models (ProtoPNets) have become the dominant model type to meet this need. Users can easily identify flaws in ProtoPNets, but fixing problems in a ProtoPNet requires slow, difficult retraining that is not guaranteed to resolve the issue. This problem is called the "interaction bottleneck." We solve the interaction bottleneck for ProtoPNets by simultaneously finding many equally good ProtoPNets (i.e., a draw from a "Rashomon set"). We show that our framework - called Proto-RSet - quickly produces many accurate, diverse ProtoPNets, allowing users to correct problems in real time while maintaining performance guarantees with respect to the training set. We demonstrate the utility of this method in two settings: 1) removing synthetic bias introduced to a bird-identification model and 2) debugging a skin cancer identification model. This tool empowers non-machine-learning experts, such as clinicians or domain experts, to quickly refine and correct machine learning models without repeated retraining by machine learning experts.
-
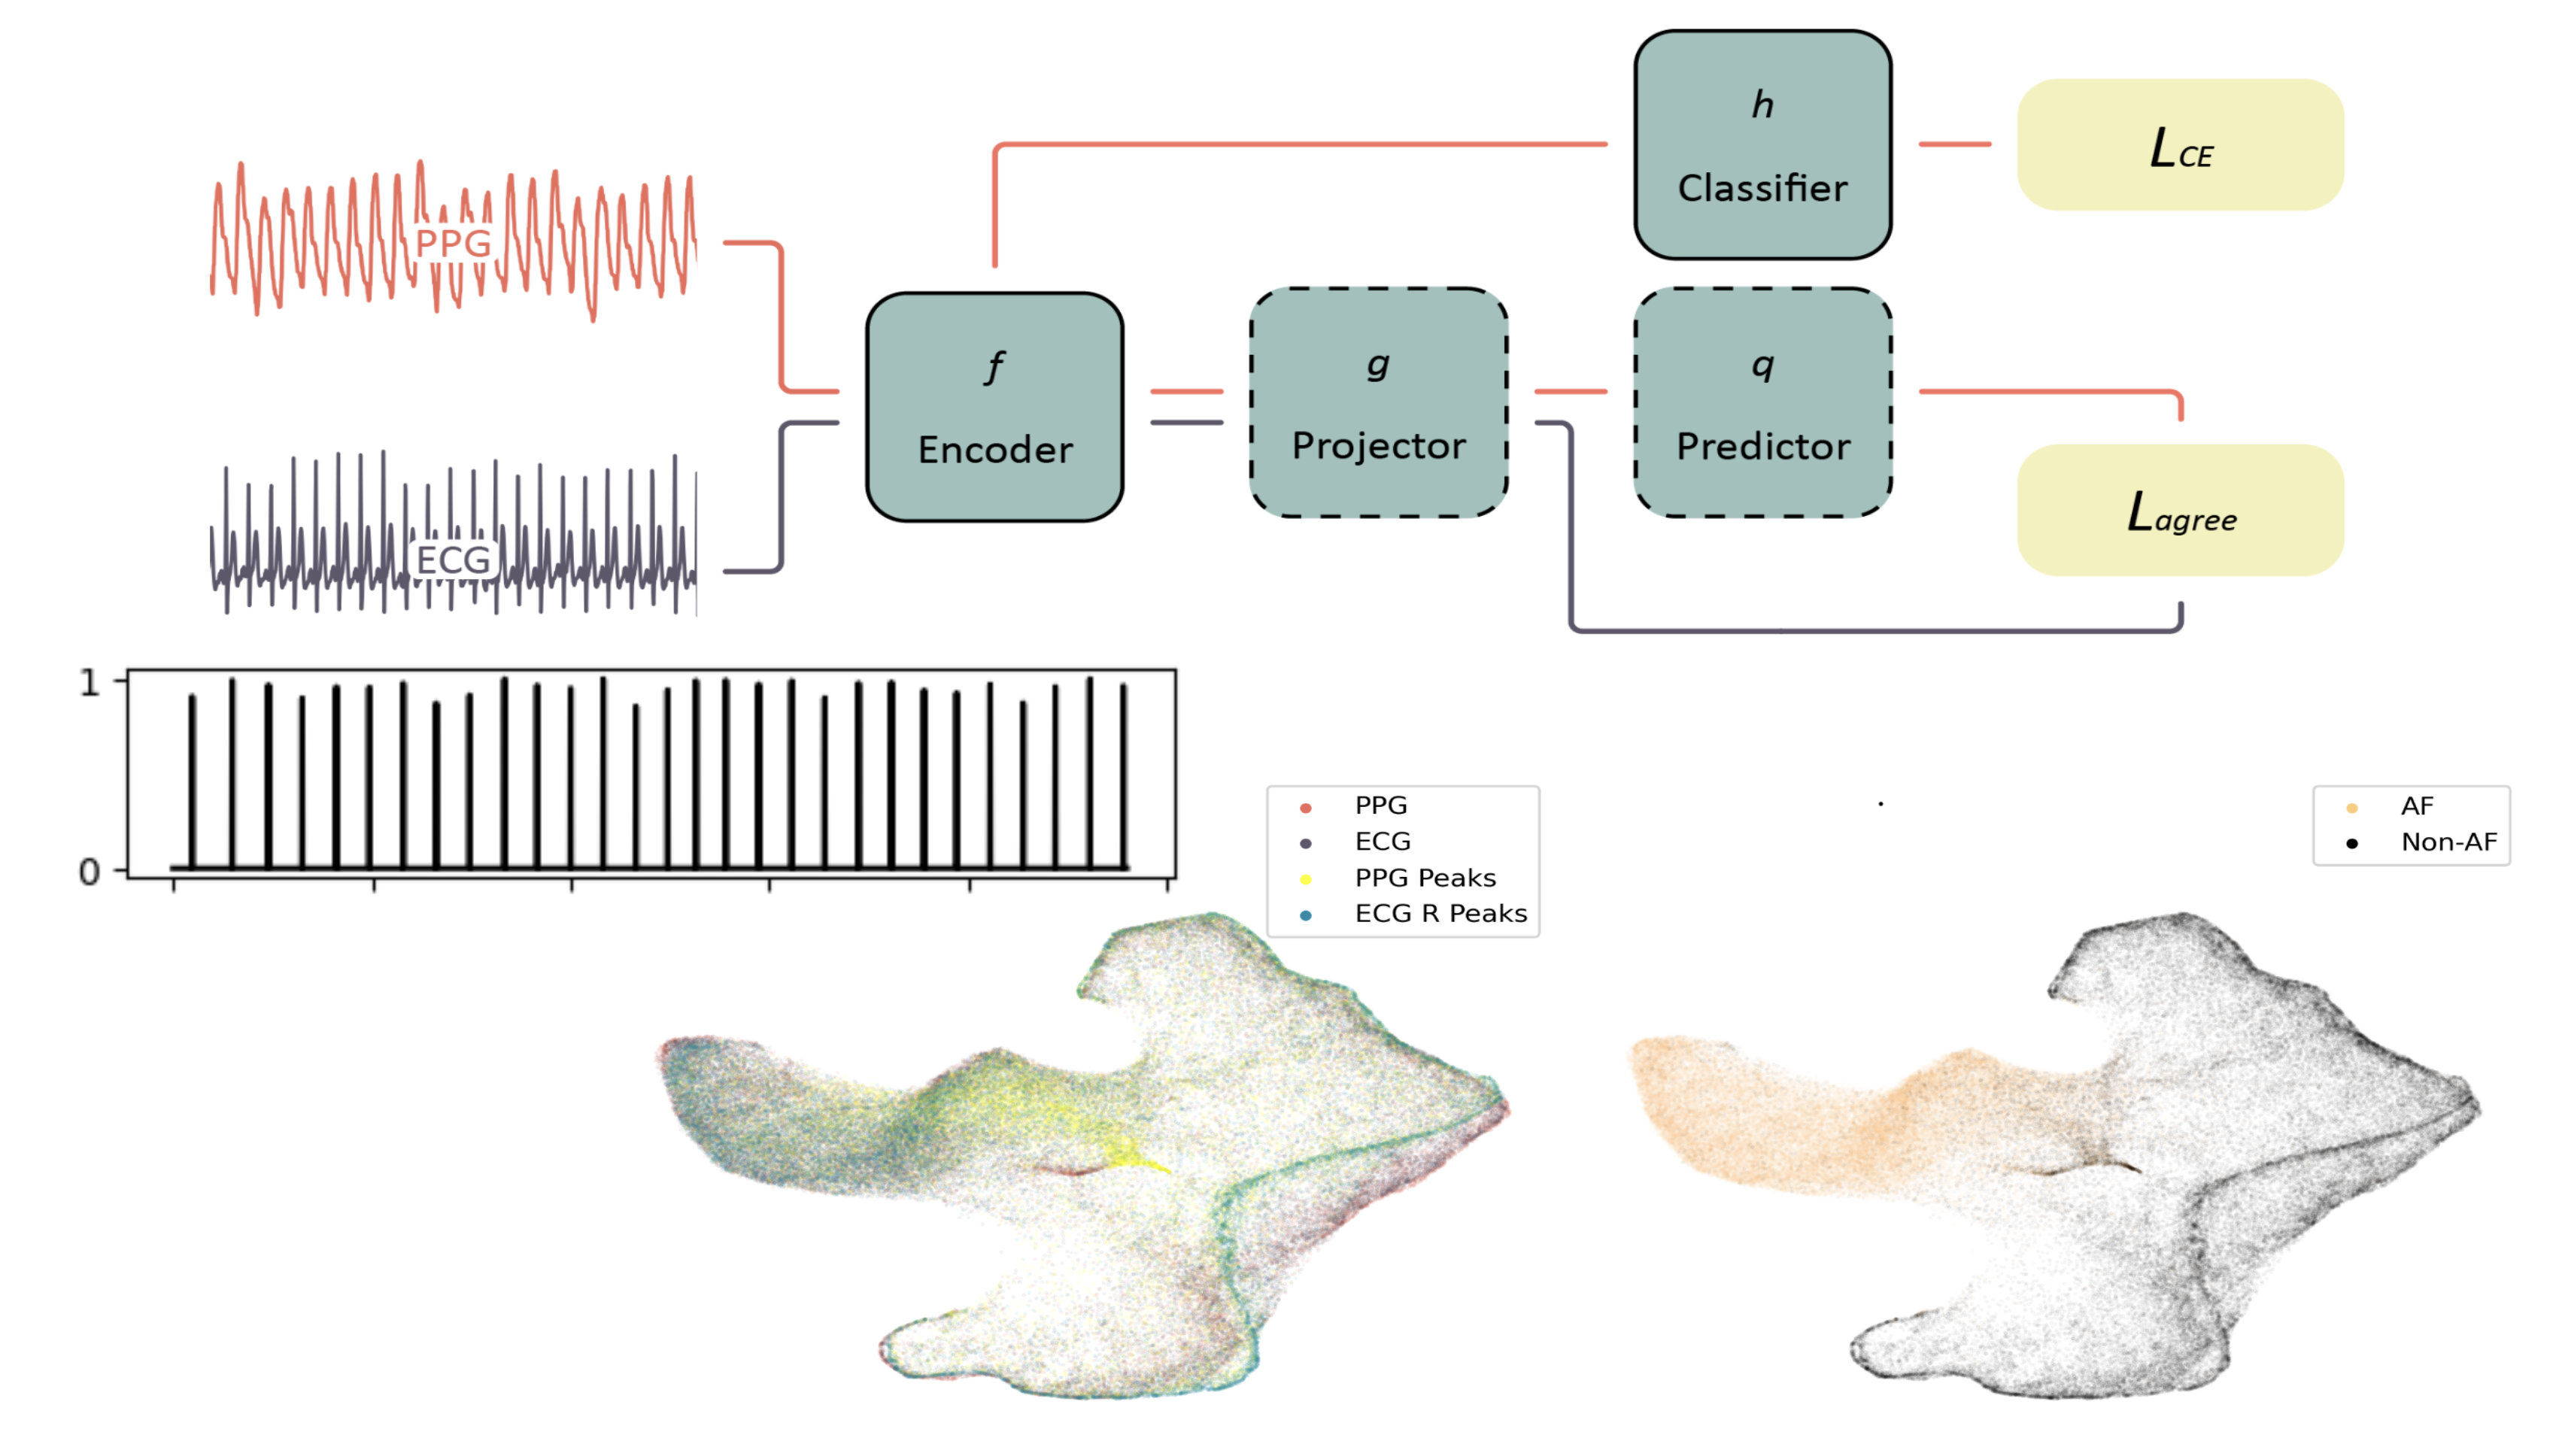 Harvard Data Science Review, 2025
Abstract
Atrial fibrillation (AF) is the most common type of cardiac arrhythmia. It is associated with an increased risk of stroke, heart failure, and other cardiovascular complications, but can be clinically silent. The wide availability of consumer wearables has made continuous AF monitoring possible thanks to built-in electrocardiogram (ECG) and photoplethysmography (PPG) sensors. ECG is the gold standard for AF diagnosis, but it cannot be passively collected on consumer devices due to its requirement that the subject is stationary, making it impractical for continuous monitoring. On the other hand, PPG offers the possibility for passive monitoring, but it is susceptible to human movements and other environmental factors, posing a significant challenge for AF detection due to noise and artifacts. Ideally, we would get the best of both worlds: the accuracy of AF detection with ECG and the broad applicability of PPG. We propose a new approach, SiamAF, to bridge the gap between ECG and PPG signals that leverages ECG and PPG signal pairs available from wearables and hospital monitors. Our method helps elevate the predictive power of the (broadly applicable but noisy) PPG signals to a level comparable to that of (less applicable but more accurate) ECG. Specifically, we train a deep neural network to learn similar information from both ECG and PPG in a contrastive fashion, which encourages it to learn medically relevant features in both ECG and PPG signals. At inference time, the proposed model is able to accurately predict AF from either PPG or ECG and outperforms baseline methods on three external test sets.


2024
-
 NEJM AI, 2024
Abstract
Background: In intensive care units (ICUs), critically ill patients are monitored with electroencephalography (EEG) to prevent serious brain injury. EEG monitoring is constrained by clinician availability, and EEG interpretation can be subjective and prone to interobserver variability. Automated deep-learning systems for EEG could reduce human bias and accelerate the diagnostic process. However, existing uninterpretable (black-box) deep-learning models are untrustworthy, difficult to troubleshoot, and lack accountability in real-world applications, leading to a lack of both trust and adoption by clinicians. Methods: We developed an interpretable deep-learning system that accurately classifies six patterns of potentially harmful EEG activity - seizure, lateralized periodic discharges (LPDs), generalized periodic discharges (GPDs), lateralized rhythmic delta activity (LRDA), generalized rhythmic delta activity (GRDA), and other patterns - while providing faithful case-based explanations of its predictions. The model was trained on 50,697 total 50-second continuous EEG samples collected from 2711 patients in the ICU between July 2006 and March 2020 at Massachusetts General Hospital. EEG samples were labeled as one of the six EEG patterns by 124 domain experts and trained annotators. To evaluate the model, we asked eight medical professionals with relevant backgrounds to classify 100 EEG samples into the six pattern categories - once with and once without artificial intelligence (AI) assistance - and we assessed the assistive power of this interpretable system by comparing the diagnostic accuracy of the two methods. The model’s discriminatory performance was evaluated with area under the receiver-operating characteristic curve (AUROC) and area under the precision-recall curve. The model’s interpretability was measured with task-specific neighborhood agreement statistics that interrogated the similarities of samples and features. In a separate analysis, the latent space of the neural network was visualized by using dimension reduction techniques to examine whether the ictal-interictal injury continuum hypothesis, which asserts that seizures and seizure-like patterns of brain activity lie along a spectrum, is supported by data. Results: The performance of all users significantly improved when provided with AI assistance. Mean user diagnostic accuracy improved from 47 to 71% (P<0.04). The model achieved AUROCs of 0.87, 0.93, 0.96, 0.92, 0.93, and 0.80 for the classes seizure, LPD, GPD, LRDA, GRDA, and other patterns, respectively. This performance was significantly higher than that of a corresponding uninterpretable black-box model (with P<0.0001). Videos traversing the ictal-interictal injury manifold from dimension reduction (a two-dimensional representation of the original high-dimensional feature space) give insight into the layout of EEG patterns within the network’s latent space and illuminate relationships between EEG patterns that were previously hypothesized but had not yet been shown explicitly. These results indicate that the ictal-interictal injury continuum hypothesis is supported by data. Conclusions: Users showed significant pattern classification accuracy improvement with the assistance of this interpretable deep-learning model. The interpretable design facilitates effective human-AI collaboration; this system may improve diagnosis and patient care in clinical settings. The model may also provide a better understanding of how EEG patterns relate to each other along the ictal-interictal injury continuum. (Funded by the National Science Foundation, National Institutes of Health, and others.)
-
 IEEE Journal of Biomedical and Health Informatics, 2024
Abstract
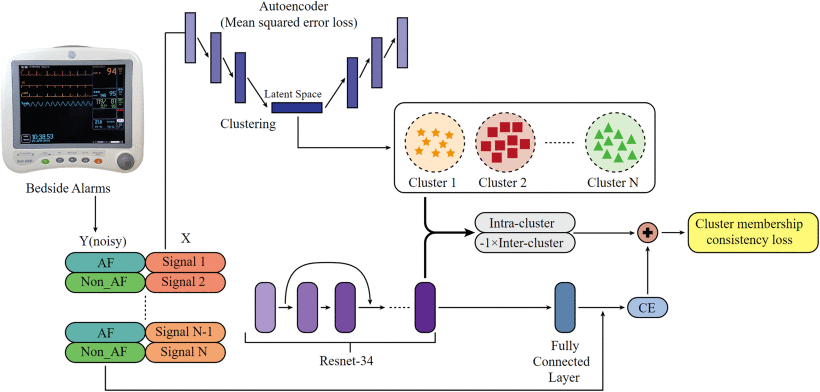
Atrial fibrillation (AF) is a common cardiac arrhythmia with serious health consequences if not detected and treated early. Detecting AF using wearable devices with photoplethysmography (PPG) sensors and deep neural networks has demonstrated some success using proprietary algorithms in commercial solutions. However, to improve continuous AF detection in ambulatory settings towards a population-wide screening use case, we face several challenges, one of which is the lack of large-scale labeled training data. To address this challenge, we propose to leverage AF alarms from bedside patient monitors to label concurrent PPG signals, resulting in the largest PPG-AF dataset so far (8.5 M 30-second records from 24,100 patients) and demonstrating a practical approach to build large labeled PPG datasets. Furthermore, we recognize that the AF labels thus obtained contain errors because of false AF alarms generated from imperfect built-in algorithms from bedside monitors. Dealing with label noise with unknown distribution characteristics in this case requires advanced algorithms. We, therefore, introduce and open-source a novel loss design, the cluster membership consistency (CMC) loss, to mitigate label errors. By comparing CMC with state-of-the-art methods selected from a noisy label competition, we demonstrate its superiority in handling label noise in PPG data, resilience to poor-quality signals, and computational efficiency.
-
 Nature Machine Intelligence, 2024
Abstract
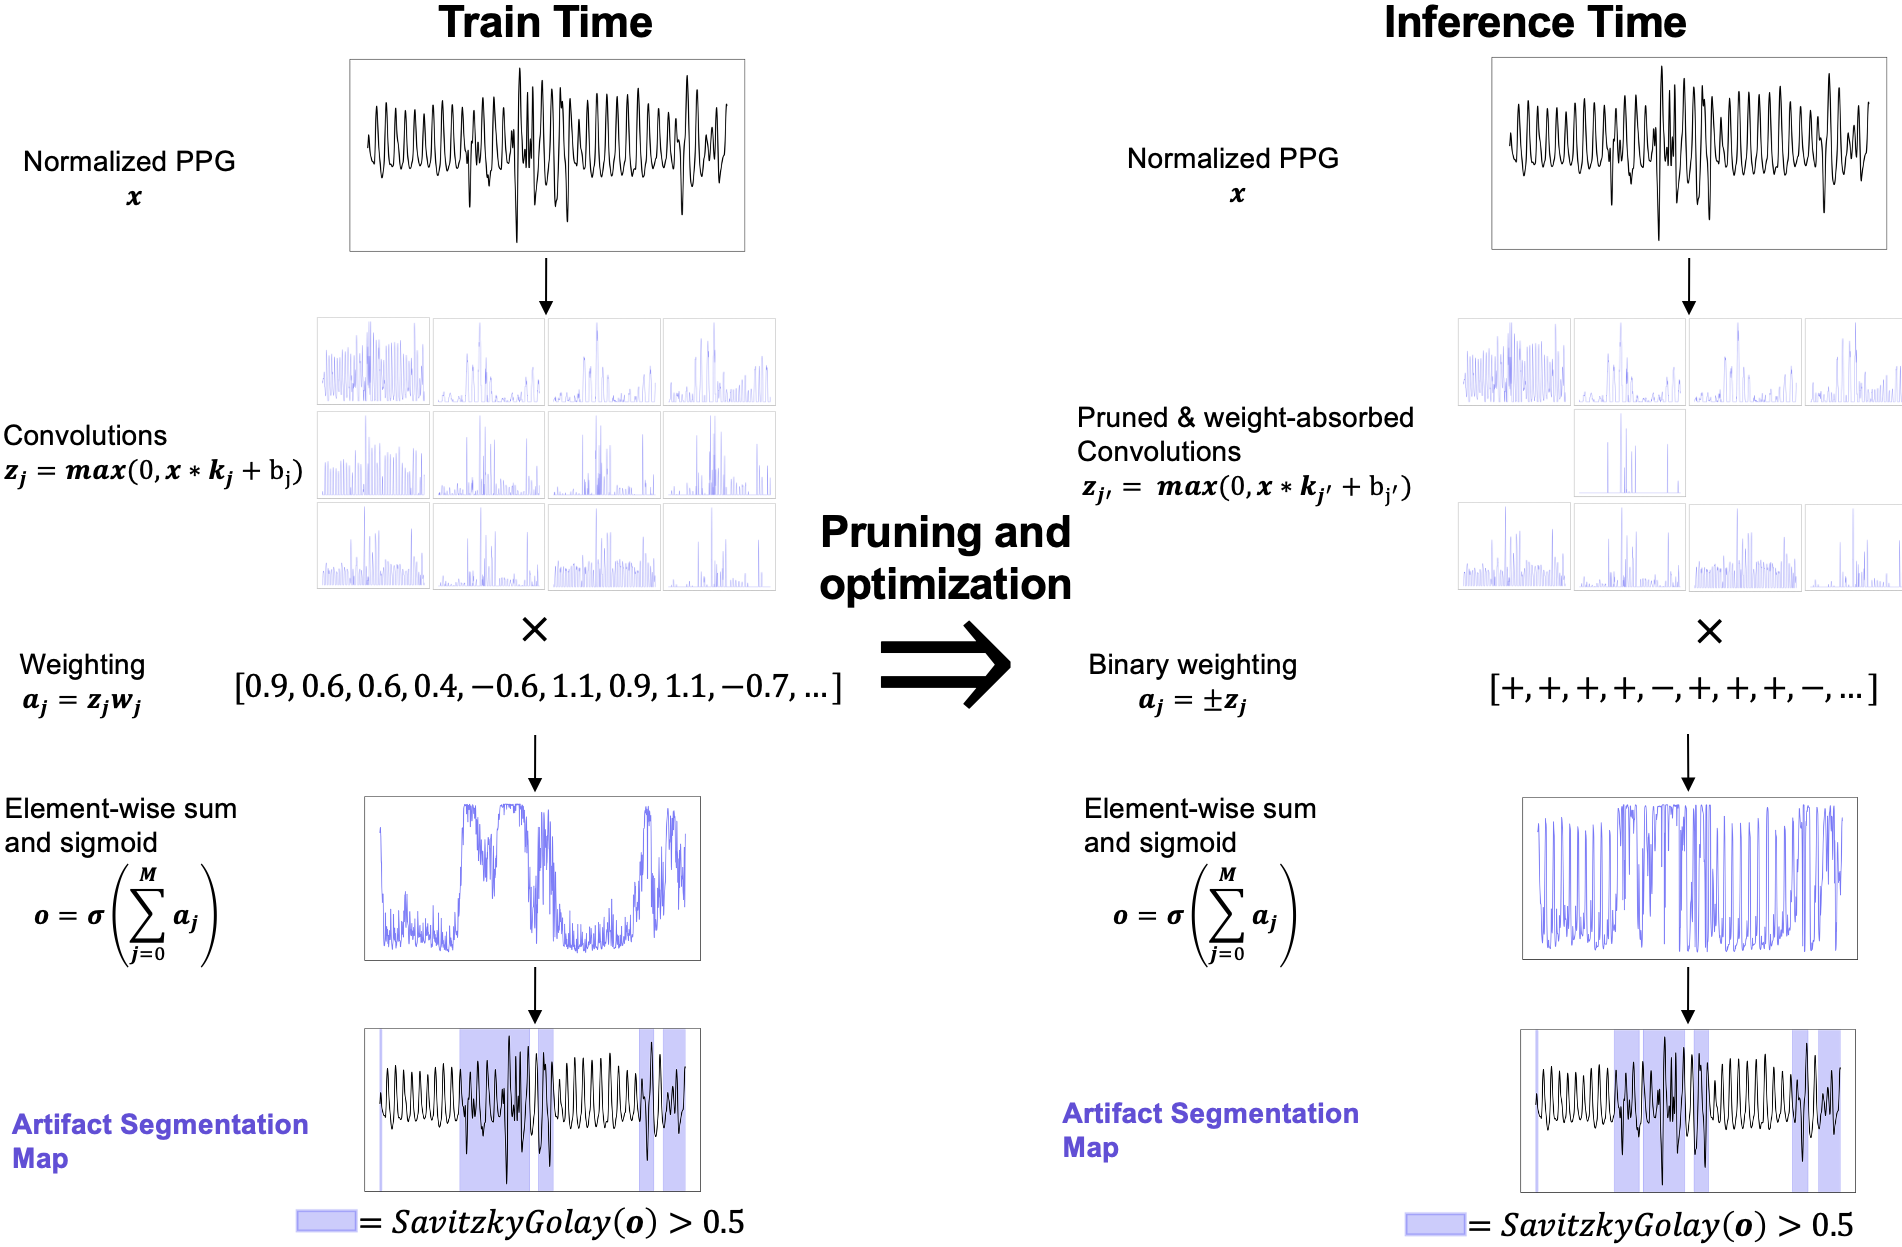
Rapid, reliable and accurate interpretation of medical time series signals is crucial for high-stakes clinical decision-making. Deep learning methods offered unprecedented performance in medical signal processing but at a cost: they were compute intensive and lacked interpretability. We propose sparse mixture of learned kernels (SMoLK), an interpretable architecture for medical time series processing. SMoLK learns a set of lightweight flexible kernels that form a single-layer sparse neural network, providing not only interpretability but also efficiency, robustness and generalization to unseen data distributions. We introduce parameter reduction techniques to reduce the size of SMoLK networks and maintain performance. We test SMoLK on two important tasks common to many consumer wearables: photoplethysmography artefact detection and atrial fibrillation detection from single-lead electrocardiograms. We find that SMoLK matches the performance of models orders of magnitude larger. It is particularly suited for real-time applications using low-power devices, and its interpretability benefits high-stakes situations.
-
 Physiological Measurement, 2024
Abstract
Objective. Physiological data are often low quality and thereby compromises the effectiveness of related health monitoring. The primary goal of this study is to develop a robust foundation model that can effectively handle low-quality issue in physiological data. Approach. We introduce SiamQuality, a self-supervised learning approach using convolutional neural networks (CNNs) as the backbone. SiamQuality learns to generate similar representations for both high and low quality photoplethysmography (PPG) signals that originate from similar physiological states. We leveraged a substantial dataset of PPG signals from hospitalized intensive care patients, comprised of over 36 million 30 s PPG pairs. Main results. After pre-training the SiamQuality model, it was fine-tuned and tested on six PPG downstream tasks focusing on cardiovascular monitoring. Notably, in tasks such as respiratory rate estimation and atrial fibrillation detection, the model’s performance exceeded the state-of-the-art by 75% and 5%, respectively. The results highlight the effectiveness of our model across all evaluated tasks, demonstrating significant improvements, especially in applications for heart monitoring on wearable devices. Significance. This study underscores the potential of CNNs as a robust backbone for foundation models tailored to physiological data, emphasizing their capability to maintain performance despite variations in data quality. The success of the SiamQuality model in handling real-world, variable-quality data opens new avenues for the development of more reliable and efficient healthcare monitoring technologies.
-
 Genomics, Proteomics & Bioinformatics, 2024
Abstract
Despite the success of antiretroviral therapy, human immunodeficiency virus (HIV) cannot be cured because of a reservoir of latently infected cells that evades therapy. To understand the mechanisms of HIV latency, we employed an integrated single-cell RNA sequencing (scRNA-seq) and single-cell assay for transposase-accessible chromatin with sequencing (scATAC-seq) approach to simultaneously profile the transcriptomic and epigenomic characteristics of ∼ 125,000 latently infected primary CD4+ T cells after reactivation using three different latency reversing agents. Differentially expressed genes and differentially accessible motifs were used to examine transcriptional pathways and transcription factor (TF) activities across the cell population. We identified cellular transcripts and TFs whose expression/activity was correlated with viral reactivation and demonstrated that a machine learning model trained on these data was 75%-79% accurate at predicting viral reactivation. Finally, we validated the role of two candidate HIV-regulating factors, FOXP1 and GATA3, in viral transcription. These data demonstrate the power of integrated multimodal single-cell analysis to uncover novel relationships between host cell factors and HIV latency.


2023
-
 arXiv preprint arXiv:2312.02300, 2023
Abstract
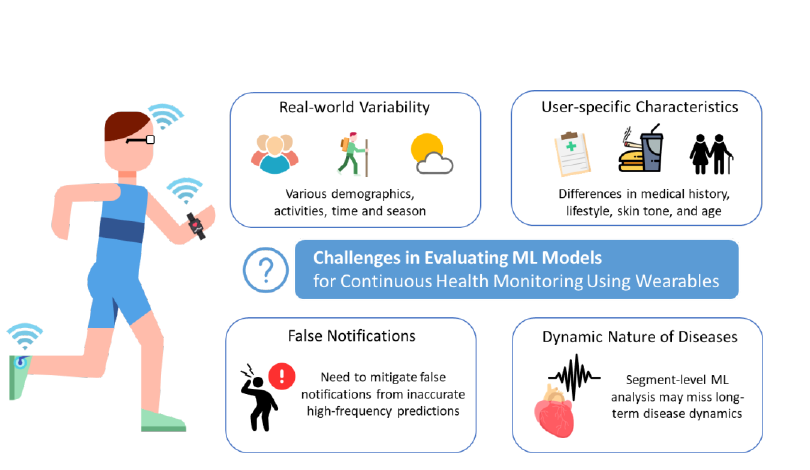
This paper explores the challenges in evaluating machine learning (ML) models for continuous health monitoring using wearable devices beyond conventional metrics. We state the complexities posed by real-world variability, disease dynamics, user-specific characteristics, and the prevalence of false notifications, necessitating novel evaluation strategies. Drawing insights from large-scale heart studies, the paper offers a comprehensive guideline for robust ML model evaluation on continuous health monitoring.

2021
-
 Physiological Measurement, 2021
Abstract
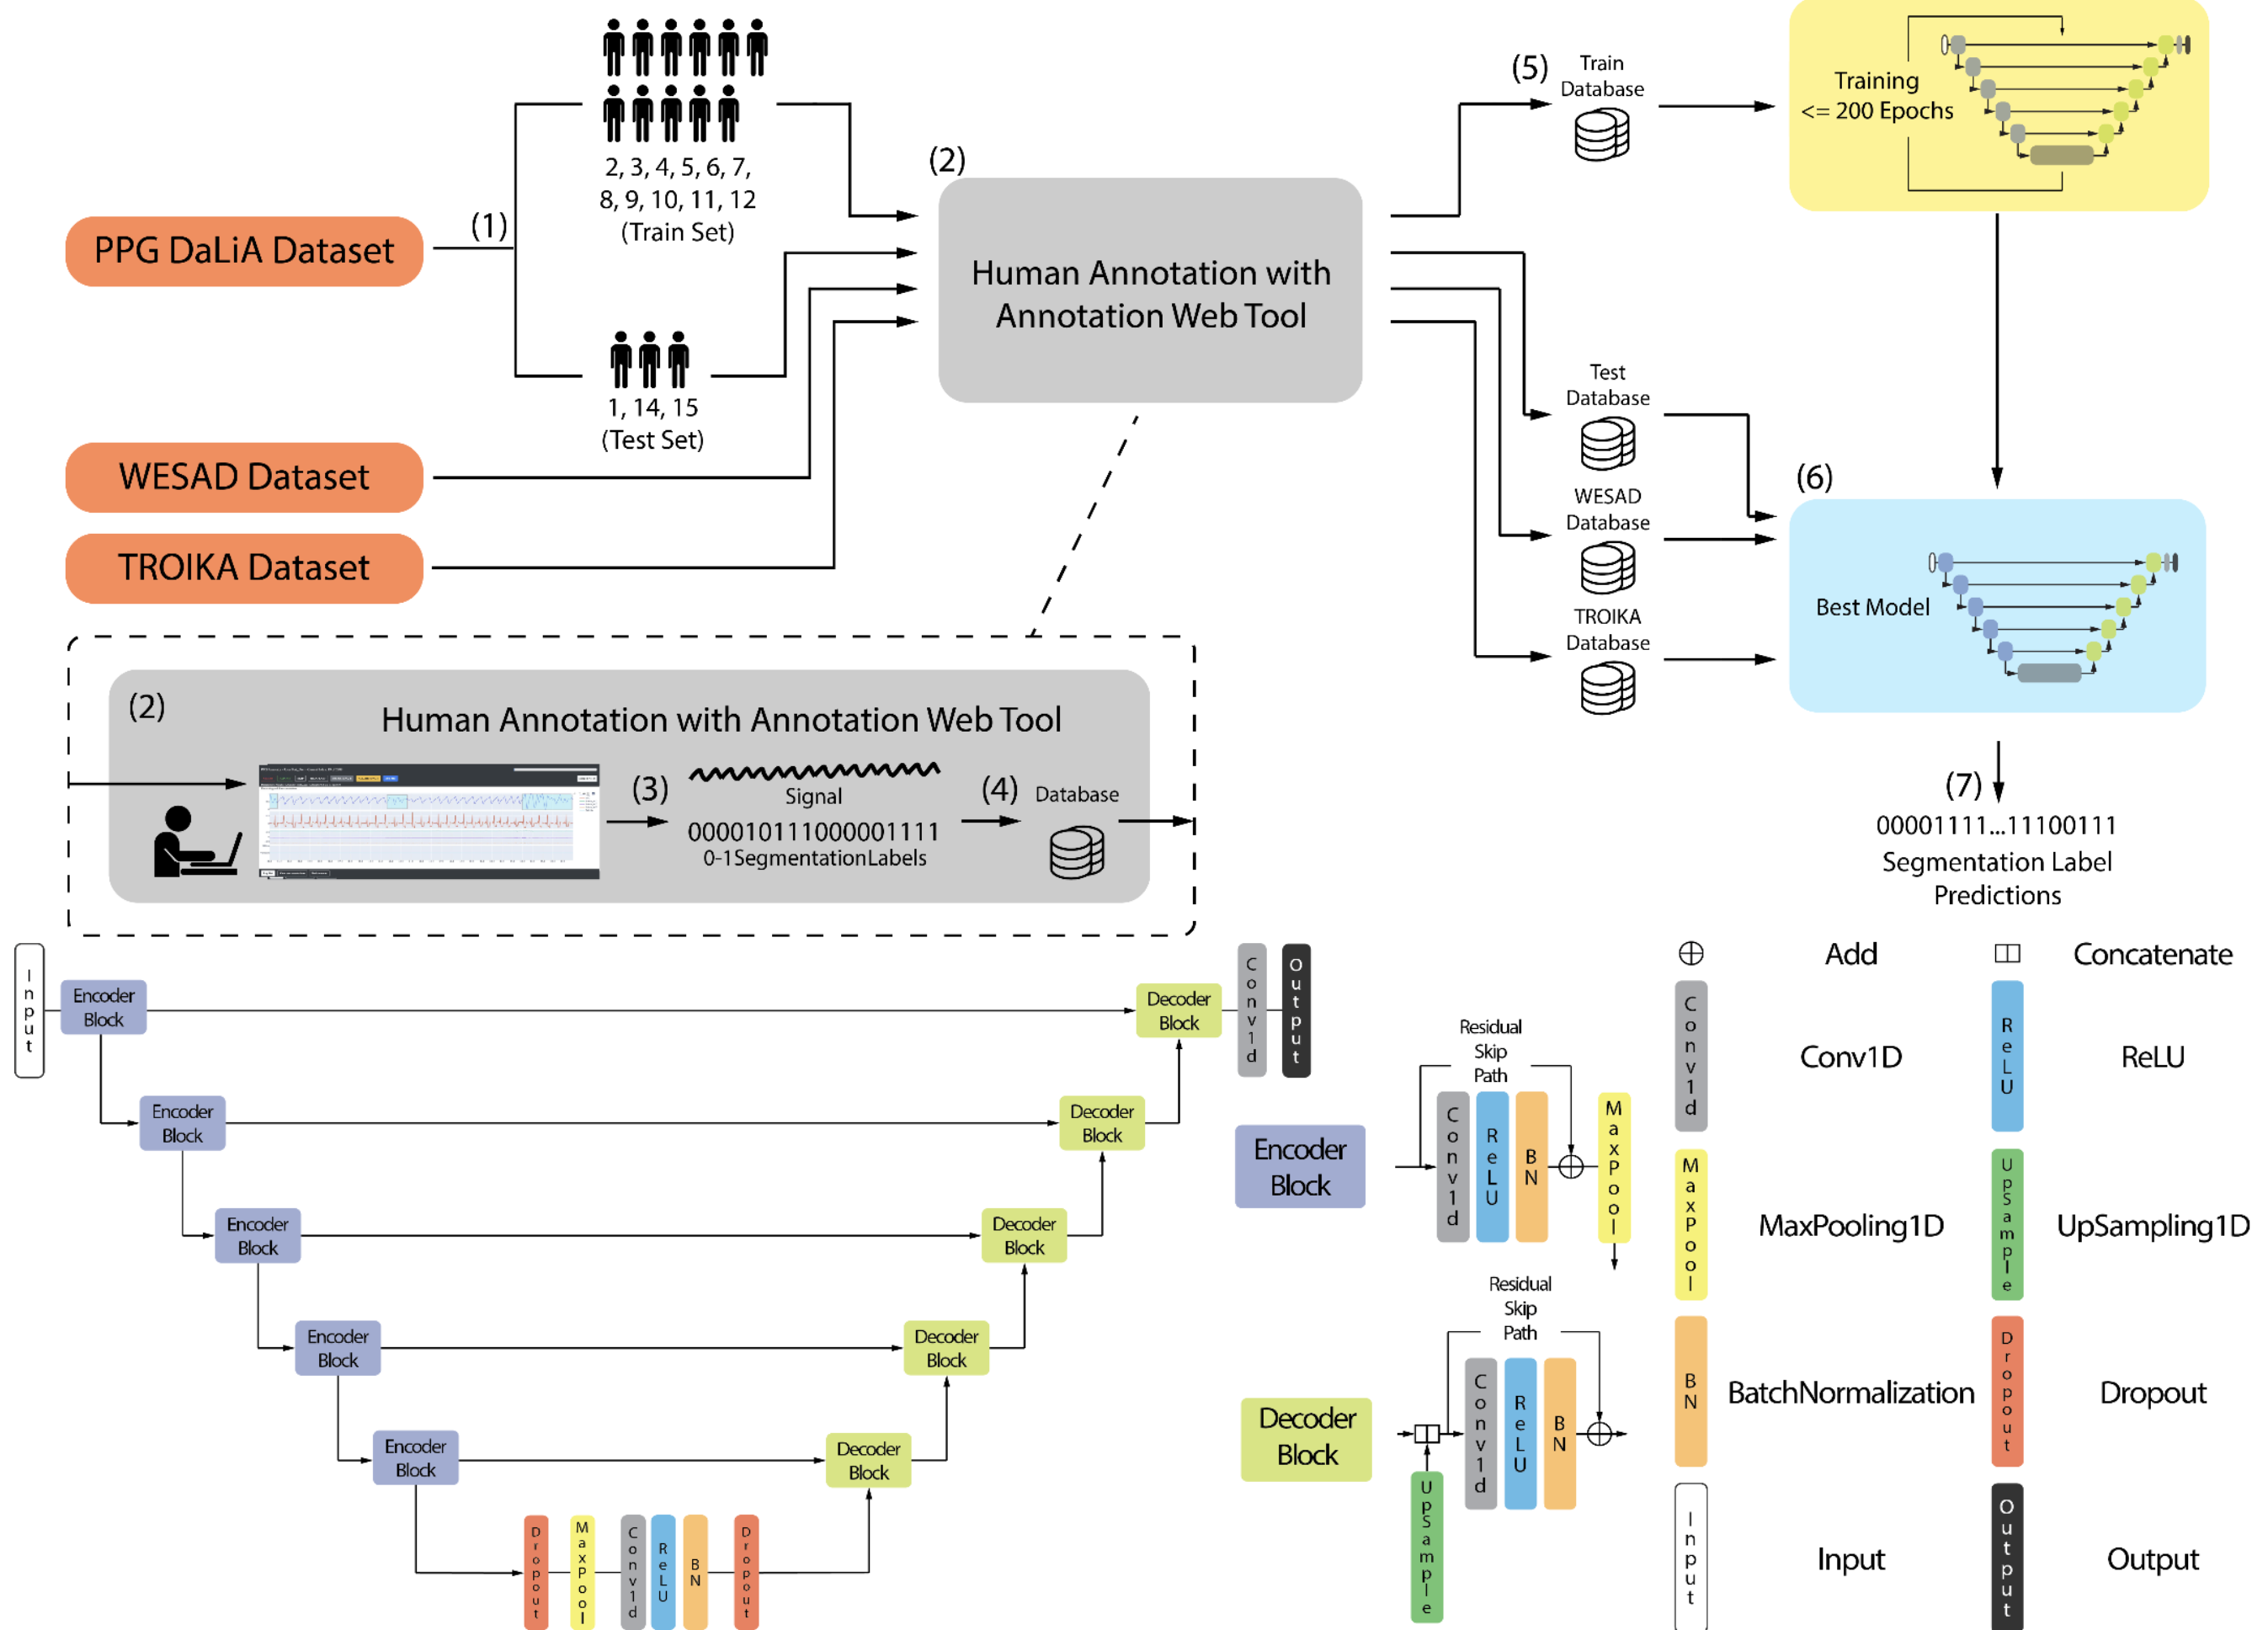
Objective. Wearable devices equipped with plethysmography (PPG) sensors provided a low-cost, long-term solution to early diagnosis and continuous screening of heart conditions. However PPG signals collected from such devices often suffer from corruption caused by artifacts. The objective of this study is to develop an effective supervised algorithm to locate the regions of artifacts within PPG signals. Approach. We treat artifact detection as a 1D segmentation problem. We solve it via a novel combination of an active-contour-based loss and an adapted U-Net architecture. The proposed algorithm was trained on the PPG DaLiA training set, and further evaluated on the PPG DaLiA testing set, WESAD dataset and TROIKA dataset. Main results. We evaluated with the DICE score, a well-established metric for segmentation accuracy evaluation in the field of computer vision. The proposed method outperforms baseline methods on all three datasets by a large margin (≈7 percentage points above the next best method). On the PPG DaLiA testing set, WESAD dataset and TROIKA dataset, the proposed method achieved 0.8734 ± 0.0018, 0.9114 ± 0.0033 and 0.8050 ± 0.0116 respectively. The next best method only achieved 0.8068 ± 0.0014, 0.8446 ± 0.0013 and 0.7247 ± 0.0050. Significance. The proposed method is able to pinpoint exact locations of artifacts with high precision; in the past, we had only a binary classification of whether a PPG signal has good or poor quality. This more nuanced information will be critical to further inform the design of algorithms to detect cardiac arrhythmia.
